TalkToTextly
Convert audio to text with AI-powered transcription.
673 results
Open the Audio & Voice category page
Convert audio to text with AI-powered transcription.
Turn words into royalty-free songs in seconds.
Launch AI Phone Agents in Minutes
Build your own AI agent in minutes, not days.
Automated user research interviews that run and analyze themselves
Autonomous AI agent that finds and qualifies leads.
Create original music in seconds with AI.
Turn YouTube videos into notes worth keeping.
Transcription for Real-World Audio 10x Lower Cost.
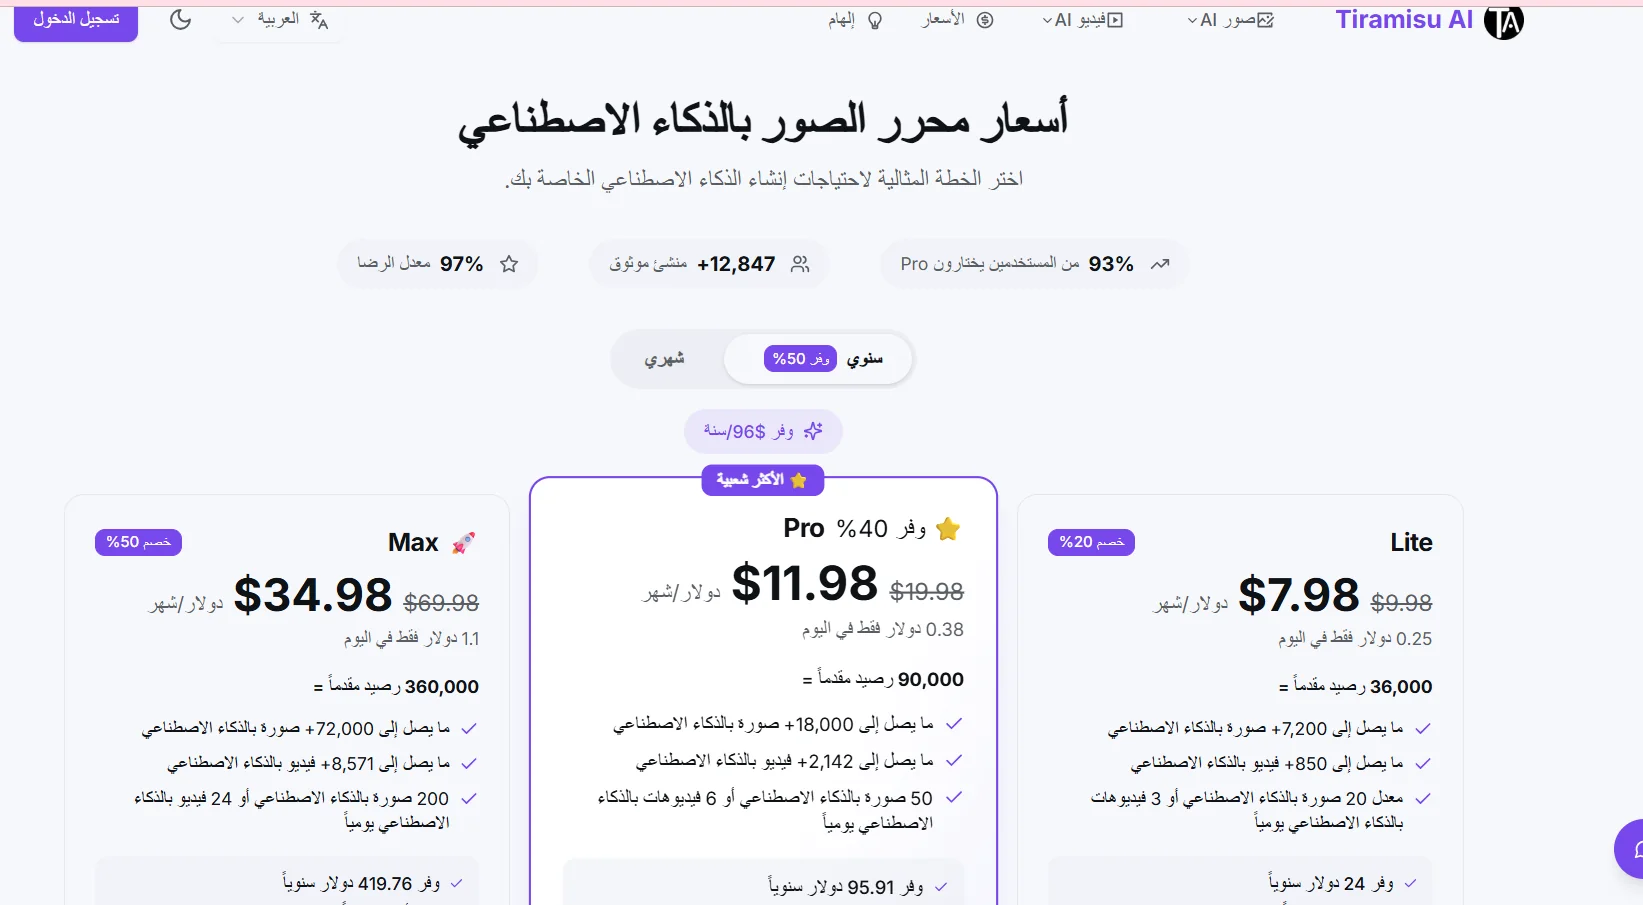
Tiramisu AI allows users to create advanced visual content using artificial intelligence, including images and videos. Content can be generated daily based on subscription plans, with specific usage quotas, and offers a variety of options to meet the needs of users ranging from beginners to professionals.
AI tools for music separation and enhancement.
Create professional AI music from text descriptions.
AI turns long videos into publish-ready Shorts.
AI generates studio-quality subtitles in minutes.
Get click-worthy YouTube titles from your video content in seconds.
Transform data into intelligent decisions instantly.
Turn anything into your learning suite.
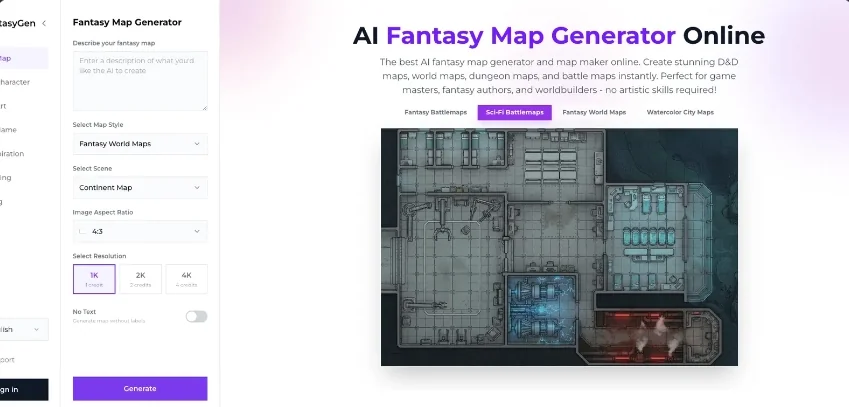
AI generator for fantasy maps, character portraits, concept art, and lore names.
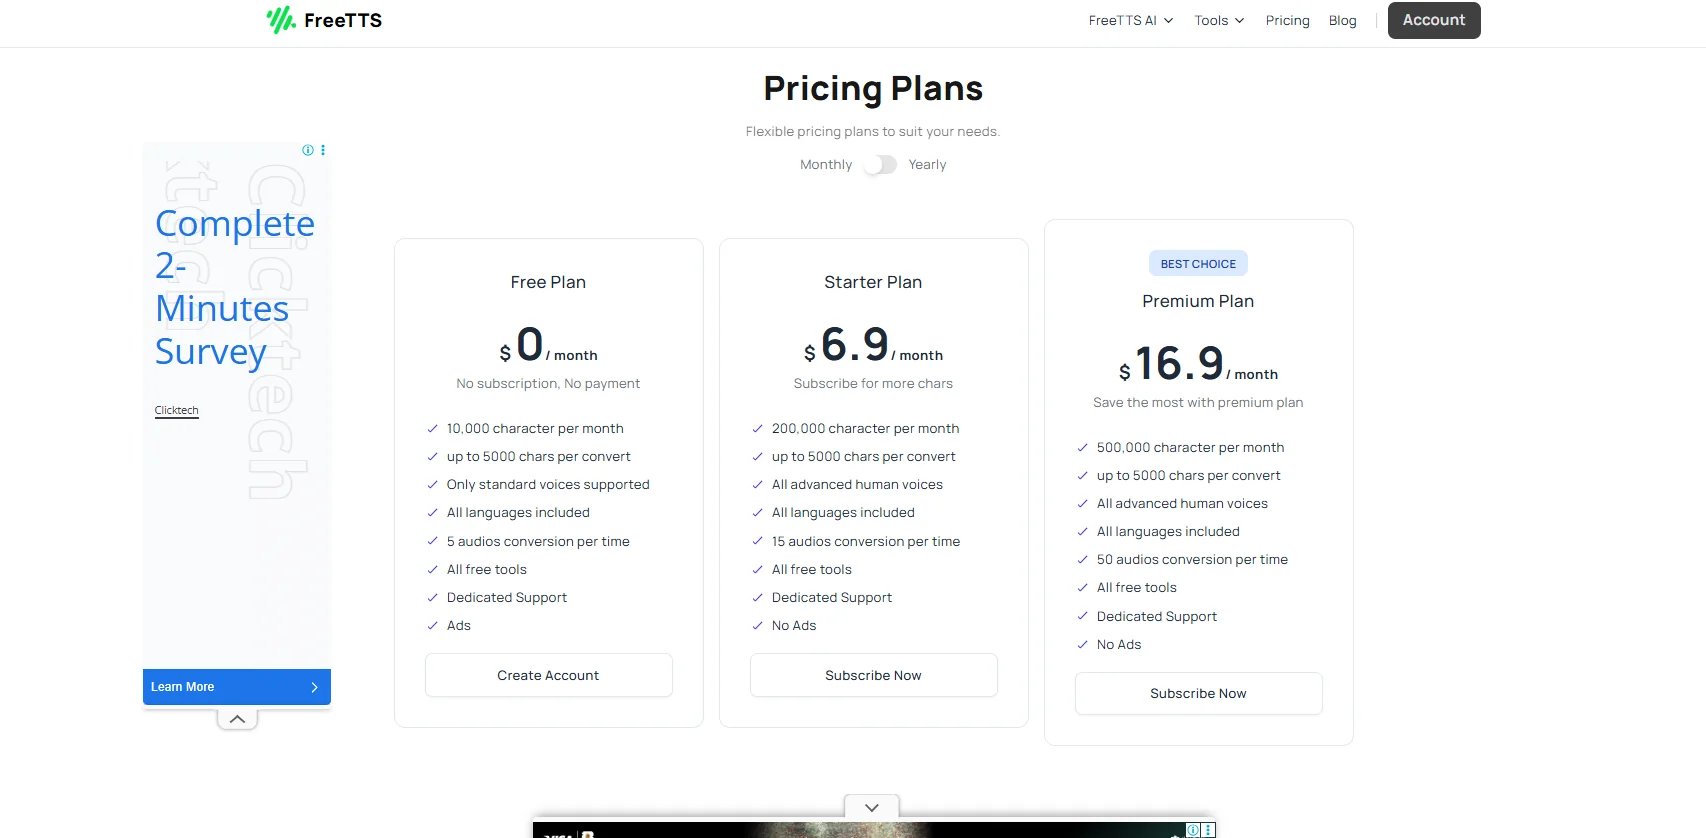
FreeTTS offers a suite of AI-powered audio processing tools, including natural-sounding text-to-speech (TTS) and highly accurate speech-to-text (STT). It allows for audio quality enhancement and noise removal using the AI Voice Enhancer, audio clipping (Audio Cutter), merging multiple audio files (Audio Joiner), and converting between different audio formats (Audio Converter). The platform is characterized by ease of use, fast performance, support for multiple formats such as MP3 and WAV, and batch processing, while maintaining user security and privacy.
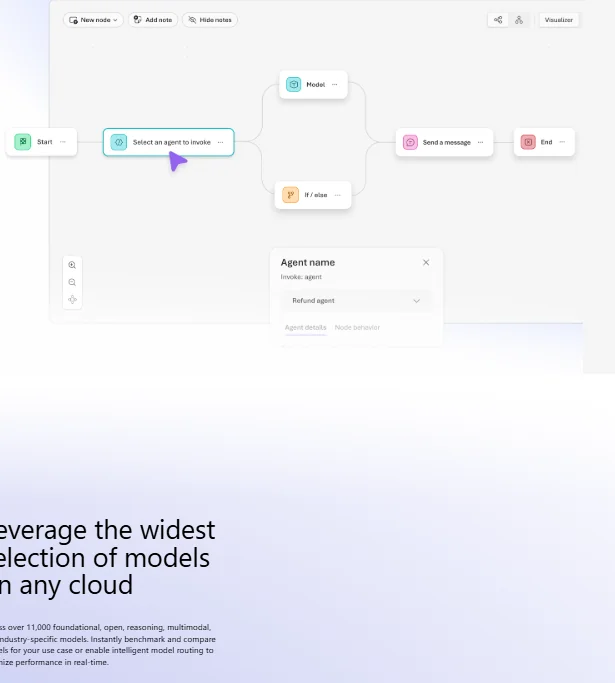
Microsoft Azure AI provides an integrated cloud platform for building professional-grade AI applications, combining infrastructure, intelligent services, and operations management within a single, scalable framework. It enables the conversion of text into realistic human speech, the creation of systems capable of accurately understanding and analyzing voice commands, and support for various applications such as voice assistants, customer service centers, and interactive voice applications. It also provides a visual development environment that allows you to connect nodes within a logical flow, with the ability to add programmatic logic, conditions, and automated actions without the need for complex programming.
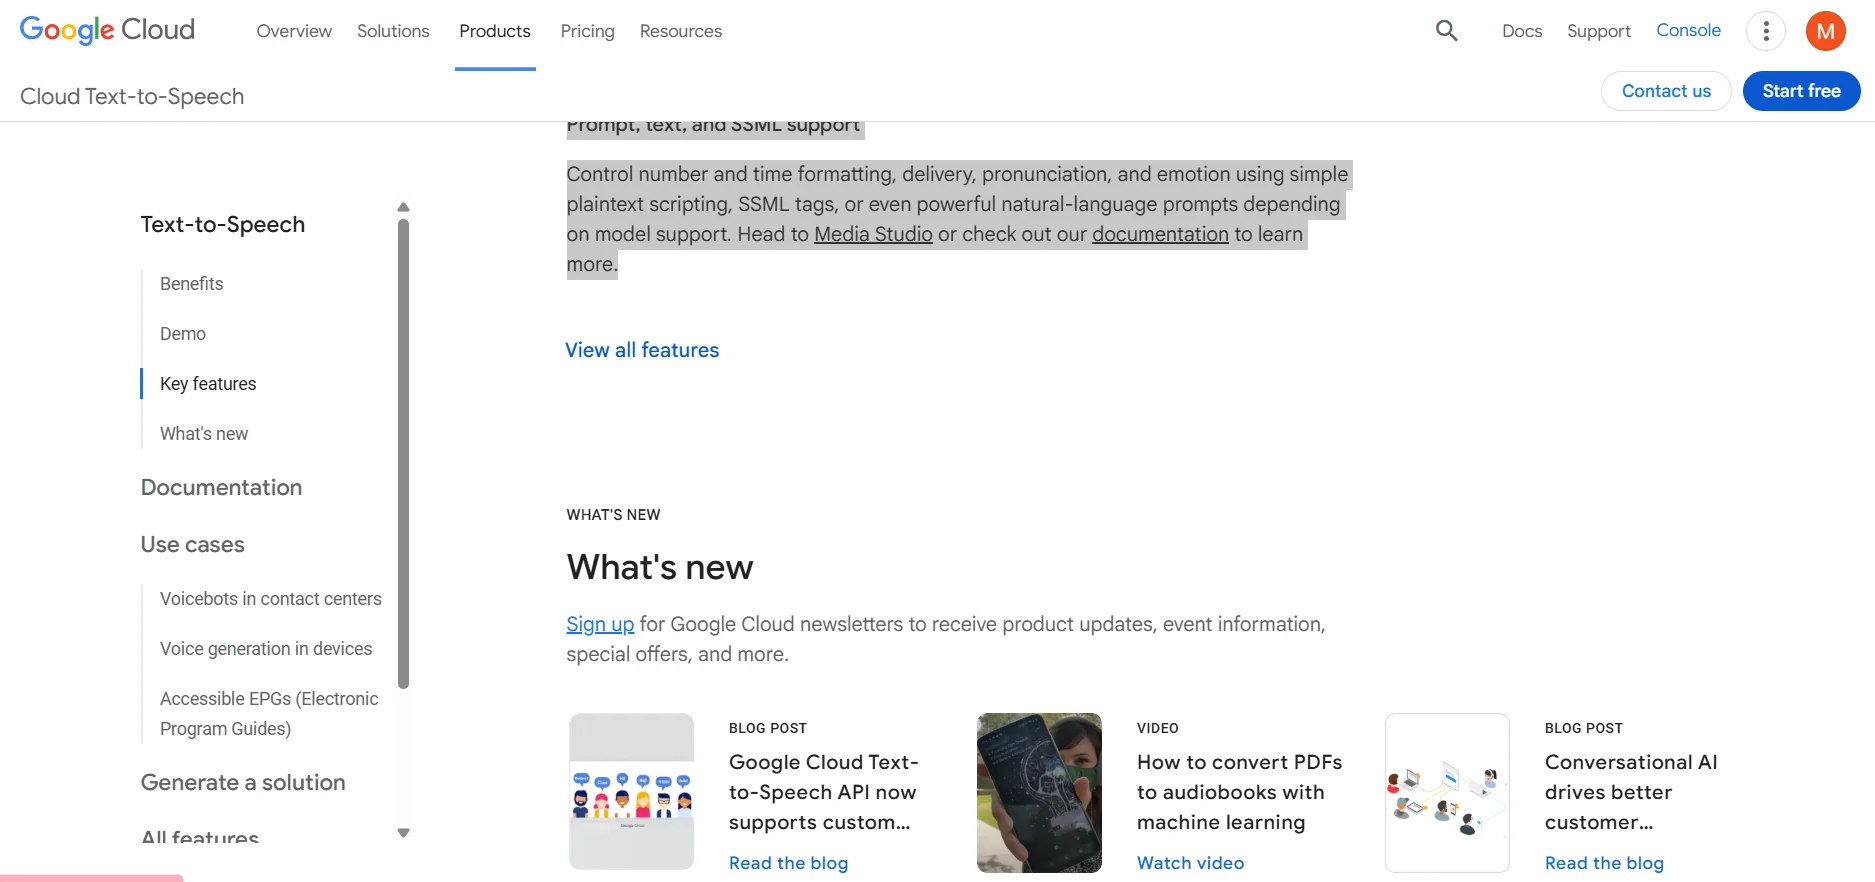
Google Cloud Text-to-Speech converts text into natural-sounding speech using an API powered by advanced AI technologies. It enables the creation of lifelike voices for apps and websites, with the ability to customize language, voice, and tone according to user preferences. The service is ideal for creating voice interfaces for apps, games, videos, podcasts, and audiobooks, with full control over pronunciation, intonation, and emotion using plain text, SSML tags, or natural language commands.
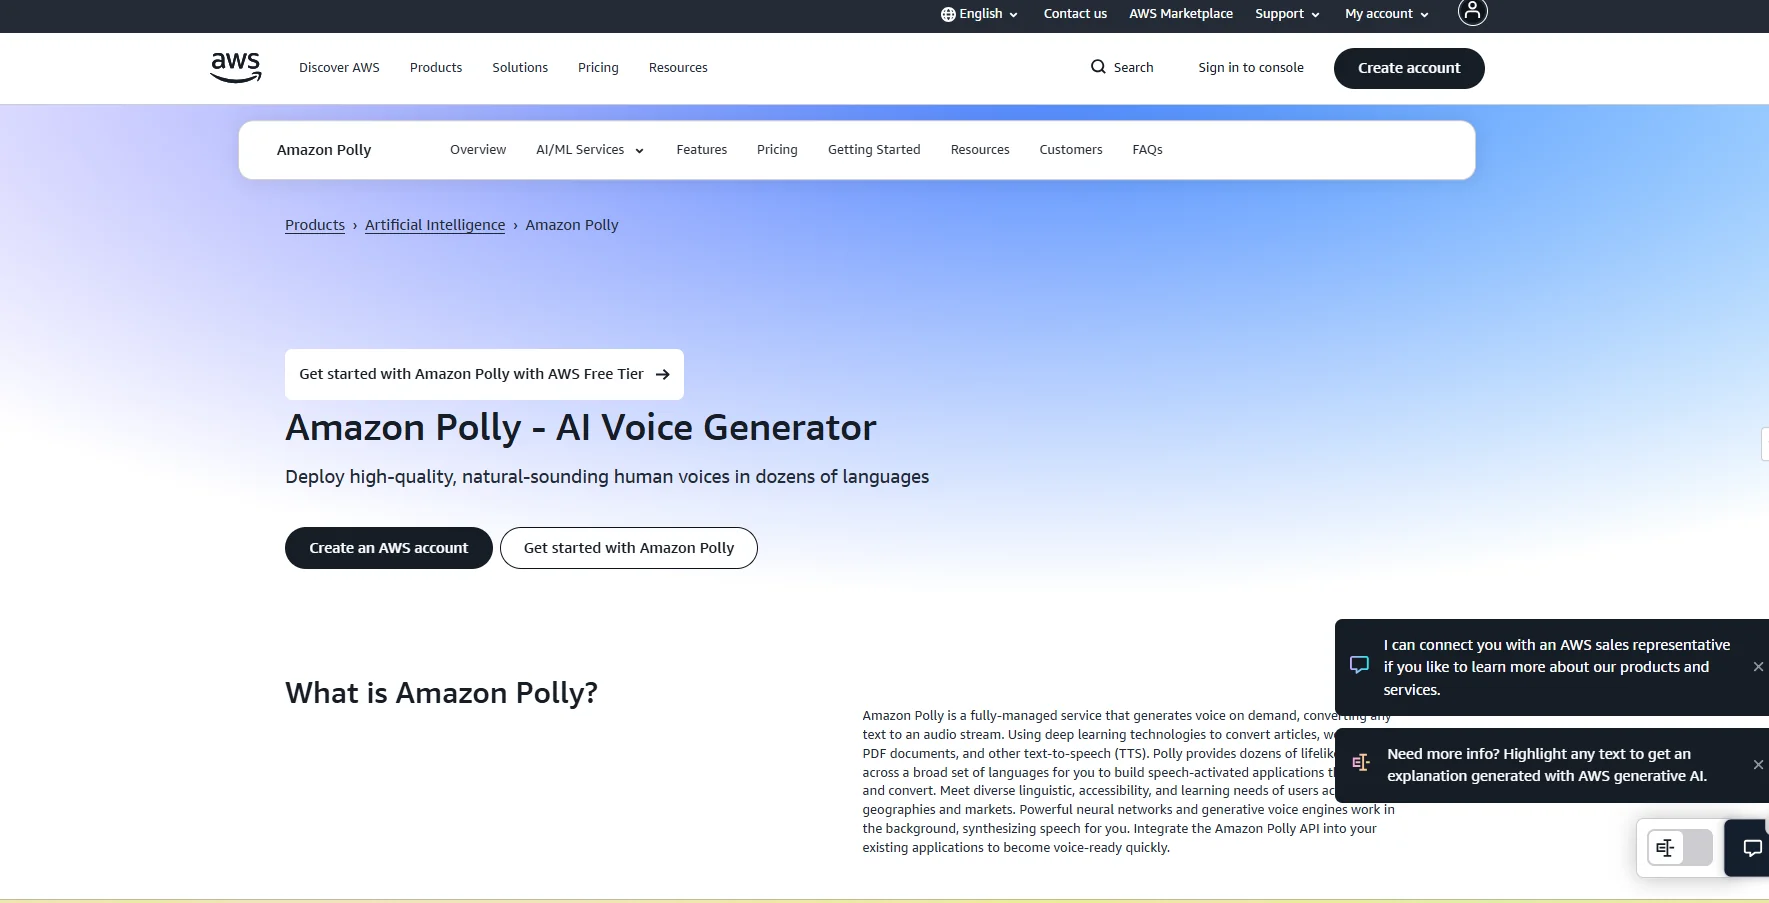
Amazon Polly enables the conversion of text into natural, high-quality human-like speech using artificial intelligence and deep learning technologies. It allows you to create multilingual voices and accents that can be used in apps, websites, and voice assistants. It supports converting various types of content, such as articles and PDF files, into audio that can be played or streamed directly, with the ability to easily integrate the service into applications via APIs to dynamically generate audio, such as for audiobooks, automated response systems, and smart assistants.
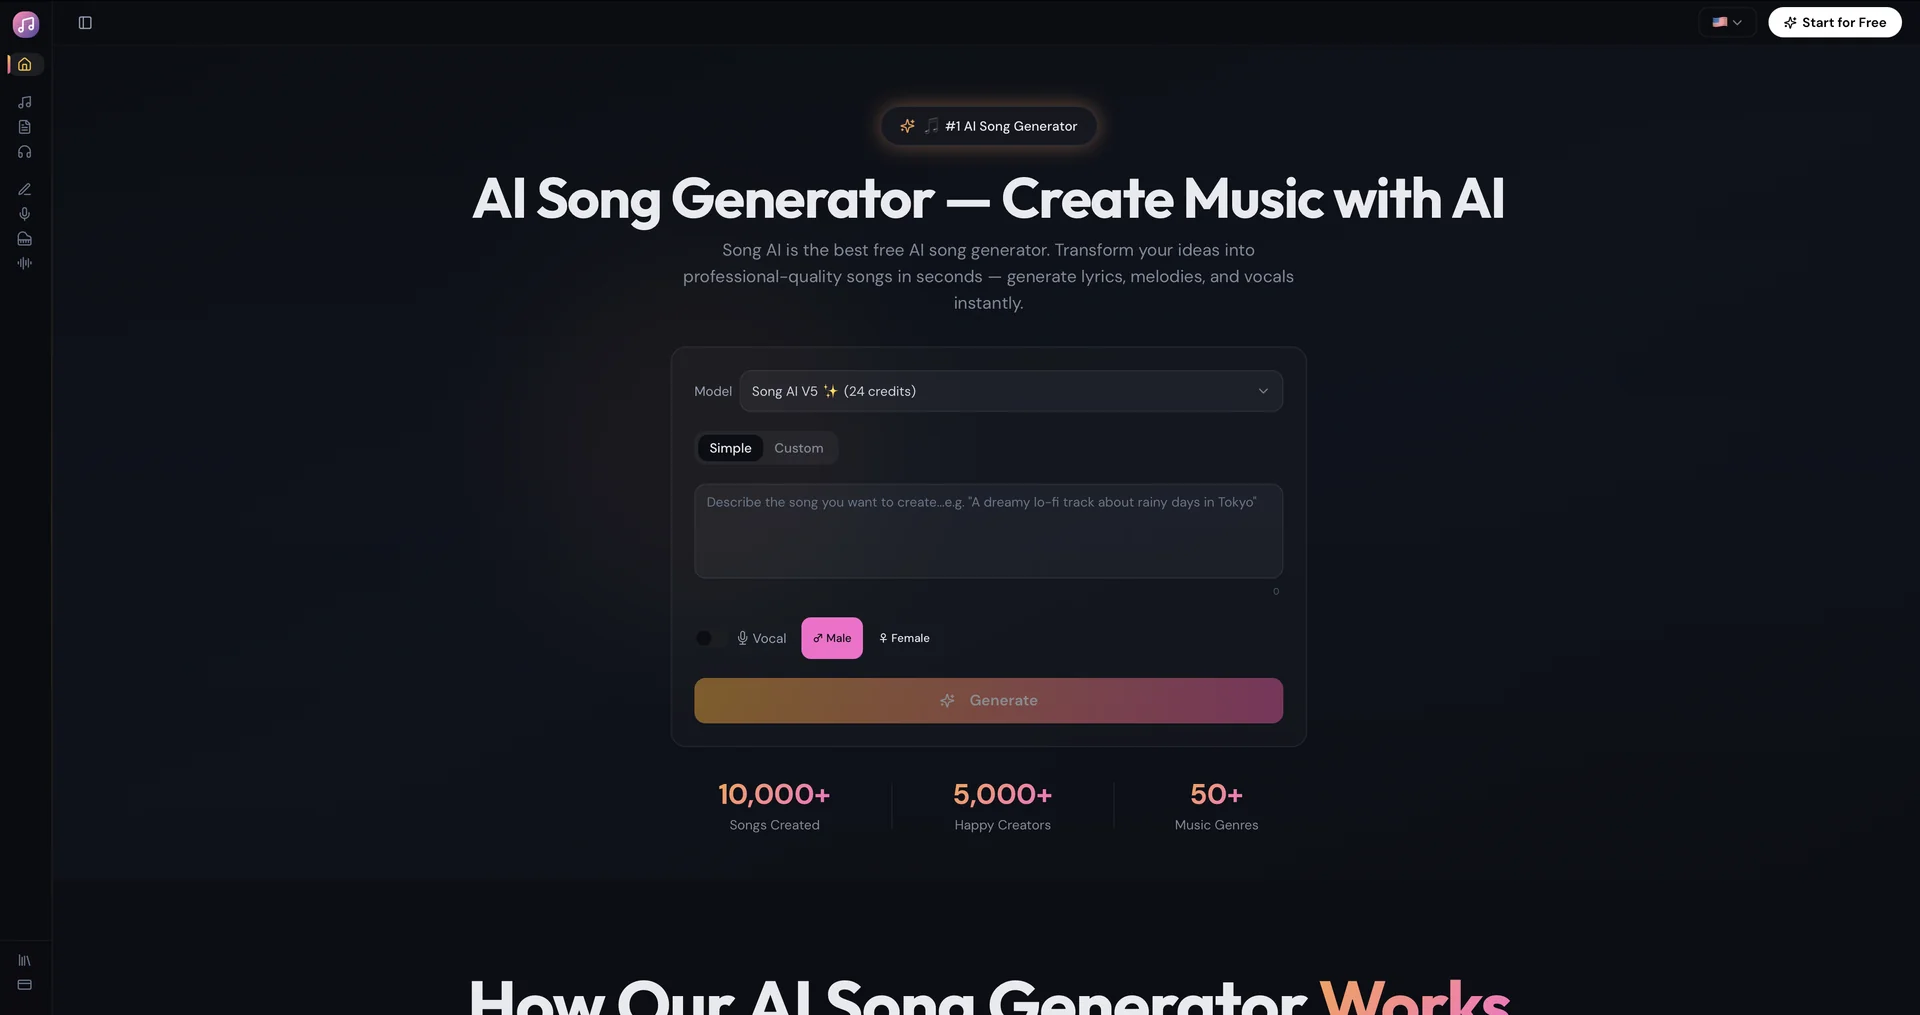
Transform ideas into professional songs in seconds.
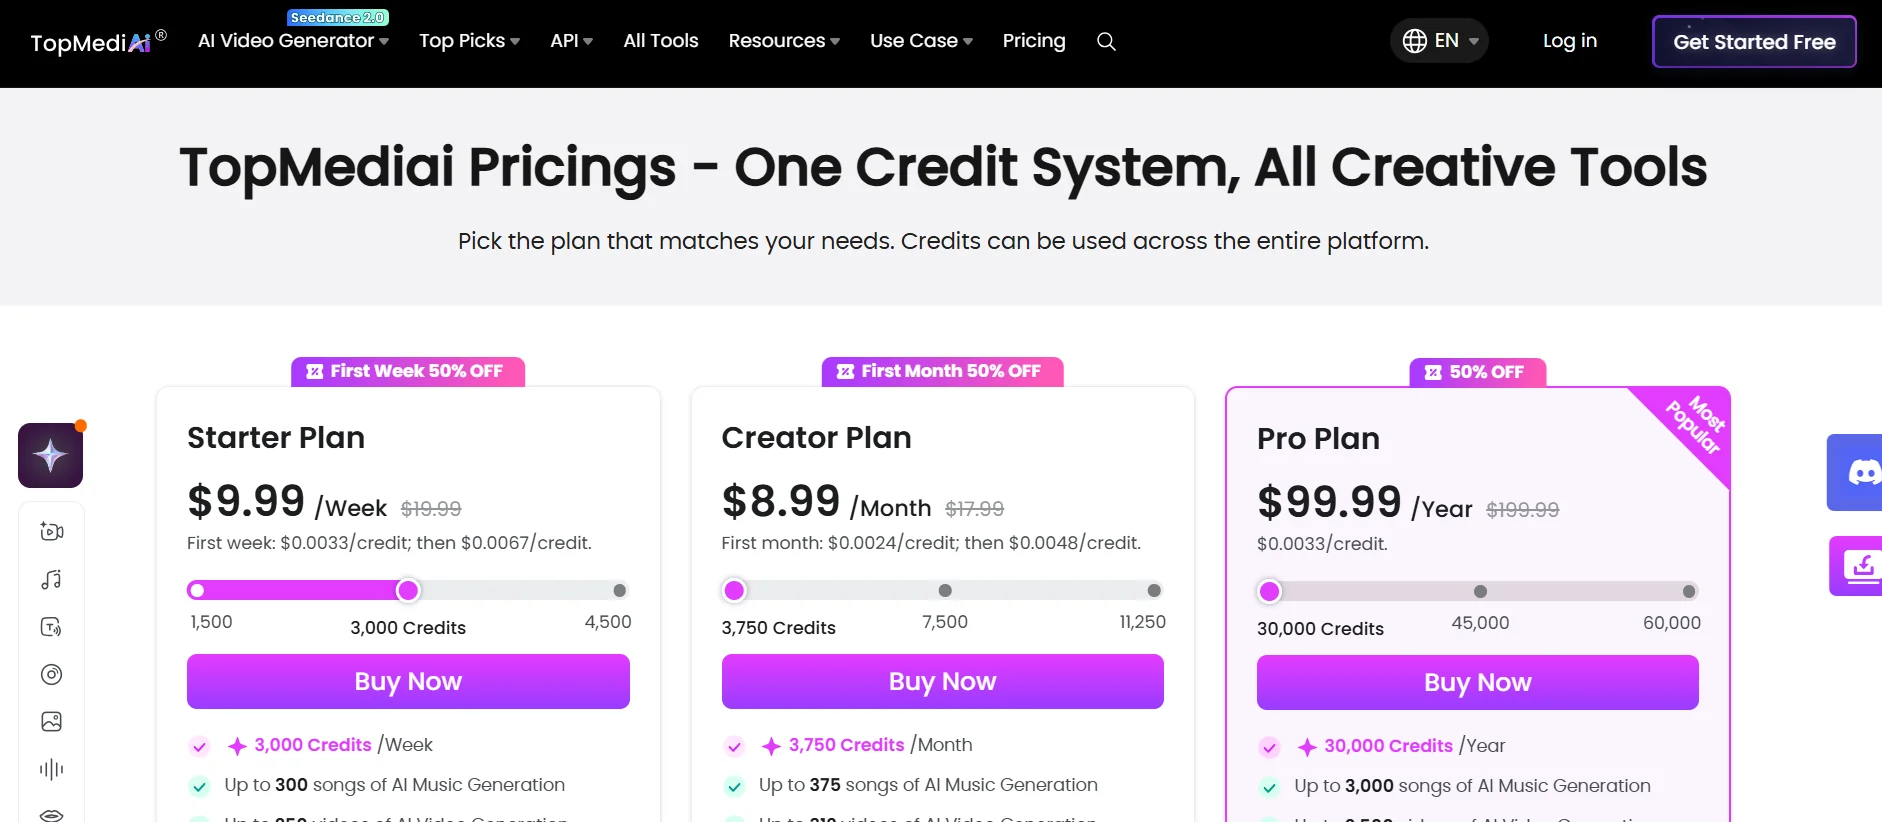
TopMediai is an integrated platform for creating audio and visual content using artificial intelligence. It enables individuals, creators, and companies to: